Cloud database? Avoid an exponentially scaling invoice
In practice It may seem ideal, the pay-as-you-go model of the Cloud, but even then the costs can get significantly…
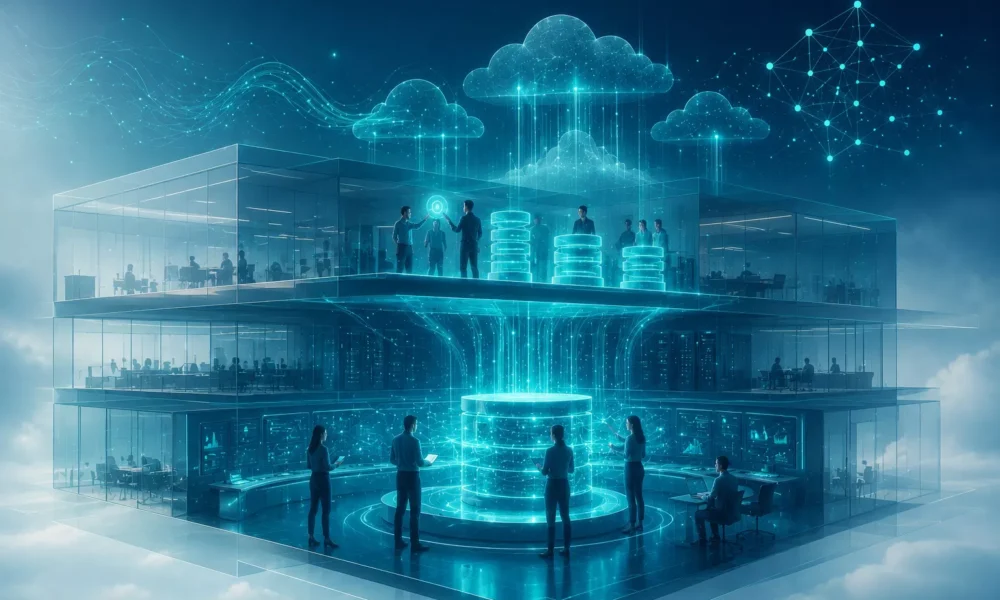
On the first floor sits the experienced DBA team. One floor up, the DevOps teams spin up databases effortlessly, without giving much thought to how they’re set up. That works fine, until it has to go into production, and the data model doesn’t scale, queries collapse under load, and resource usage spirals out of control. Now that organizations are investing heavily in AI, that problem is only getting more visible, because AI is only ever as good as the data foundation it runs on. The knowledge to prevent all this was in the same building the whole time, one floor down, just never at the table.
Gerard Zuidweg, Managing Partner at OptimaData, runs into this picture often. In this blog, he explains why the data layer is exactly what determines, right now, whether a platform scales or grinds to a halt.
The database used to be the heart of every system. At a lot of organizations, it’s since been demoted to a checkbox on a provisioning screen, and that’s happened right at the moment the data layer is what determines whether systems work well and scale efficiently. I actually understand quite well how it got to this point. The attention didn’t just vanish overnight. It happened gradually, and each of the reasons behind it makes sense on its own.
It started with automating the standard tasks: patching, backups, provisioning, replication settings. Managed services like RDS, Aurora, Cloud SQL, and Azure SQL were the logical next step: cloud providers bundled that automation into a ready-made service. In users’ experience, the database became a non-issue. A few clicks and you’ve got a running engine. It feels like something that just happens on its own, and that’s nice.
At the same time, the classic DBA role dissolved into DevOps, and that happened in two steps. The infrastructure DBA became largely redundant: the cloud provider now handles patching, backups, replication, and high availability just as well, and often cheaper. But the application DBA (the person who thought alongside the development team about the data model, schema design, and indexing strategy) disappeared right along with it, with nothing equivalent taking its place. Deep database knowledge was no longer explicitly owned anywhere. It became everyone’s responsibility, and therefore nobody’s.
Meanwhile, the application layer is pulling all the attention toward itself. ORMs like Prisma, Hibernate, and Entity Framework abstract SQL away entirely. Developers have started thinking in objects and endpoints, not query plans and isolation levels. The database becomes the place where the ORM puts its stuff. The schemaless wave reinforced that: with schemaless, the idea took hold that careful data modeling wasn’t necessary anymore.
On top of that comes time-to-market. Spinning up a PostgreSQL database takes minutes and works fine, at small scale. The problem is that the cost of choices like that doesn’t disappear. It gets deferred, and it comes back, rarely as tidy technical debt. Usually as a crisis: a cloud bill spiraling out of control, latency you can’t get rid of anymore, lock contention that brings the whole platform to its knees under load.
So where should all that database knowledge actually sit? Exactly at the point where it makes the difference, today, between a platform that scales and one that grinds to a halt.
The data model is the most durable part of your system. You refactor code in a sprint. A data migration at scale is a project with real risk, downtime, and a rollback plan. In our experience, teams pick the wrong order: build the application first, figure out how the data fits underneath it later. Whoever puts access patterns and the data model at the front of the design instead builds a foundation that lasts for years, rather than one that needs tearing up again in eighteen months. That ordering choice isn’t just a detail. It’s the difference between building on top and starting over.
The lion’s share of performance and cost problems originate in the data layer. Think instances sized far too generously, missing indexes, N+1 queries the ORM quietly multiplies into thousands of round trips, full table scans on tables that only keep growing, and connection pooling that’s set up wrong. These aren’t footnotes: this is exactly where the invoice comes from. That also explains why a lot of FinOps tooling falls short: it looks at the invoice, not at the query plans causing it. Whoever actually looks at the query plans can see why the bill is climbing. Only once you know that cause, instead of just the symptom, can you actually fix it structurally.
Then there’s AI, the reason this topic is surfacing again instead of sinking further out of view. RAG, vector search, and agentic workloads are only ever as good as the data flows underneath them. Data quality, structure, retrieval performance, governance, and lineage suddenly become the deciding factor in whether an AI initiative delivers something, or turns into an expensive disappointment. AI exposes a messy data layer mercilessly. You can put the best model you want on top of it, but if the foundation is crooked, the walls start cracking.
The market declared the database a commodity right at the moment AI turned it back into a critical factor.
There’s a nuance here worth pointing out. It’s not really about which database you choose anymore; that part has largely become commoditized, and there’s nothing wrong with that. Managed services are fine. The attention has shifted to how well your data layer is designed, measured, and managed. That’s where the difference actually sits. And that’s exactly the knowledge that’s been quietly leaking out of organizations over the past few years: dissolved into DevOps, abstracted away by the ORM, clicked past on a provisioning screen.
Whoever still has that knowledge in-house, or knows how to organize it, builds efficient, durable solutions. That builds a real advantage. And that’s exactly what we at OptimaData have been doing for years: bringing the data layer back to where it belongs, as the beating heart underneath your applications, your cloud, and your AI.
This blog is the starting point of a series. Over the coming weeks, we’ll take on the themes from this piece one by one: why AI projects run aground on the data layer, how to avoid paying for bored GPUs, what NIS2 means the moment you connect AI to your database, and why enterprise AI doesn’t need a new database silo of its own.
Don’t want to wait, and just want to know whether your data foundation is ready for what you’re planning to do with it? That’s what the AI Data Readiness QuickScan is for. Within a few days, you’ll know where you stand, with a clear report and concrete next steps. Feel free to get in touch, even if you’re not a client yet. We’re happy to think it through with you.